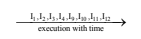Computer System Architecture MCQ - Pipeline and Vector Processing

Correct AnswerOption D
Rate difficulty Rate difficulty:
Choose a difficulty.
pipelining

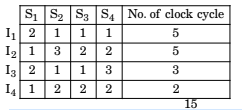
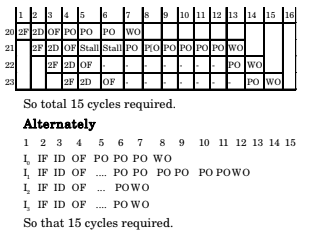
1st time for loop required is cycle and again second time 15 cycle
So, total = 30 cycle
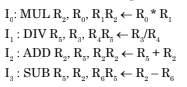
Cancel reply

Your email address will not be published. Required fields are marked *


Cancel reply

Your email address will not be published. Required fields are marked *

Correct AnswerOption B
Rate difficulty Rate difficulty:
Choose a difficulty.
Found this useful?
Follow:
Clocks
pipelining

Cancel reply

Your email address will not be published. Required fields are marked *


Cancel reply

Your email address will not be published. Required fields are marked *

Correct AnswerOption B
Rate difficulty Rate difficulty:
Choose a difficulty.
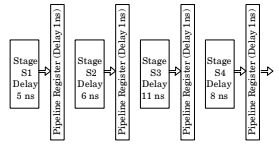
Pipeline registers overhead is not counted in normal time execution
So the total count will be
5 + 6 + 11 + 8 = 30 [without pipeline]
Now, for pipeline, each stage will be of 11 n-sec (+ 1 n-sec for overhead).
and, in steady state output is produced after every pipeline cycle. Here, in this case 11 n-sec. After adding 1n-sec overhead, We will get 12 n-sec of constant output producing cycle.
dividing 30/12 we get 2.5
Cancel reply

Your email address will not be published. Required fields are marked *


Cancel reply

Your email address will not be published. Required fields are marked *

Correct AnswerOption C
Rate difficulty Rate difficulty:
Choose a difficulty.
Register renaming is done to eliminate WAR/WAW hazards.
Cancel reply

Your email address will not be published. Required fields are marked *


Cancel reply

Your email address will not be published. Required fields are marked *

Correct AnswerOption A
Rate difficulty Rate difficulty:
Choose a difficulty.
Given: Five stage instruction pipeline Delays for FI, DI, FO, EI and WO are 5, 7, 10, 8, 6 ns resp.
To find: Time needed to execute 12 instruction prog.
Analysis: Since the max. time taken by any stage is 10 ns and additional 1 ns is required for delay of buffer. Therefore total time for an instruction to pass from one stage to another is 11ns. Now instructions are executed as follows:

pipelining
Now when I4 is in its execution stage we detect the branch and when I4 is in WO stage we fetch I9 so time for execution of instructions from I1 to I4 is = 11*5 + (4 – 1)*11 = 88 ns.
And time for execution of instructions from I9 to I12 is = 11*5 + (4 – 1)*11 = 88 ns. = 88 ns. But we have 11ns when fetching I9 i.e. I9 requires only 44 ns additional instead of 55 ns because time for fetching I9 can be overlap with WO of I4.
Hence total time is = 88 + 88 – 11 = 165 ns

Cancel reply

Your email address will not be published. Required fields are marked *


Cancel reply

Your email address will not be published. Required fields are marked *

Why Practice with Avatto?
High Quality MCQsExam-focused questions with accurate answers
Detailed ExplanationsStep-by-step explanations to enhance learning
Latest Exam PatternBased on updated syllabus and pattern
Performance AnalyticsTrack performance and improve weak areas
100% Free PracticePractice unlimited questions for free
Boost Your PreparationAttempt mock tests, previous year papers and topic-wise quizzes.Explore All Tests →