


Translations Look aside Buffer can be accessed
during effective address calculations.
Computer System Architecture MCQ - Pipeline and Vector Processing
Pipelining does not increase the execution time
of a single instruction. It increases the overall
performance by executing instructions in multiple
pipeline stages.
For N=1
Pipelined CPU :
Total time (T1) = (K + (N – 1)) * T = KT
Non-Pipelined CPU :
Total time (T2) = KNT = KT
Considering buffer delays in pipelined CPU,
T1 > = T2
For N=1
Pipelined CPU :
Total time (T1) = (K + (N – 1)) * T = KT
Non-Pipelined CPU :
Total time (T2) = KNT = KT
Considering buffer delays in pipelined CPU,
T1 > = T2
Pipelining is a method to execute a program
breaking it in several independent sequence of
stages.
In that case pipeline stages can’t have different delays, no dependency among consecutive instructions and sharing of hardware resources should not be there.
In that case pipeline stages can’t have different delays, no dependency among consecutive instructions and sharing of hardware resources should not be there.
4
Consider a pipelines processor with 4 stages S1 to S4. We want to execute the following loop : for (i = 1, i < = 1000; i++) {I1, I2, I3, I4} where the time taken (in ns) by instructions I1 to I4 for stages S1 to S4 are given below
The output of I1 for i = 2 will be available after
| S1 | S2 | S3 | S4 | |
| I1 : | 1 | 2 | 1 | 2 |
| I2 : | 2 | 1 | 2 | 1 |
| I3 : | 1 | 1 | 2 | 1 |
| I4 : | 2 | 1 | 2 | 1 |
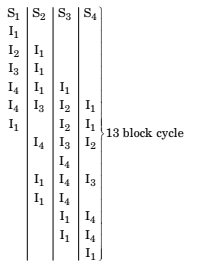
Delay is 5 nanosecond/stage.
Total delay in pipeline = 150 + 120 + 160 + 140
= 570
Delay due to stage delay = 15
Total delay = 585
Total time taken = 1000 data item size/585ns
= 165.5 microsecond
Total delay in pipeline = 150 + 120 + 160 + 140
= 570
Delay due to stage delay = 15
Total delay = 585
Total time taken = 1000 data item size/585ns
= 165.5 microsecond
